I watched a video on YouTube titled "Best Ways to Run Qwen3.8-27B on Dual RTX 5060 Ti Cards" and it said "measured 78.31 tokens/second for prose and 124.89 tokens/second". So I tried it.
https://github.com/skrodahl/qwen38-27B-dual-rtx5060
I gave it a prompt like this.
Design a project for an "On-device motion classification and anomaly alert system" that integrates an ESP32-P4 board, I2C/SPI based IMU (acceleration/gyro) sensor, and Wi-Fi functionality.
Contents to include:
FreeRTOS-based multi-tasking design guide for collecting sensor data at a 50Hz rate and storing it in a queue or buffer
Framework for time series data (CNN/LSTM) inference and TFLite Micro execution code
Network integration code that transmits JSON data via HTTP POST or MQTT over Wi-Fi when anomalies such as 'fall' are detected
Tips for preventing memory leaks and debugging in a multi-tasking environment
It took about 418 seconds.
Observing with the dashboard created by Gemini...
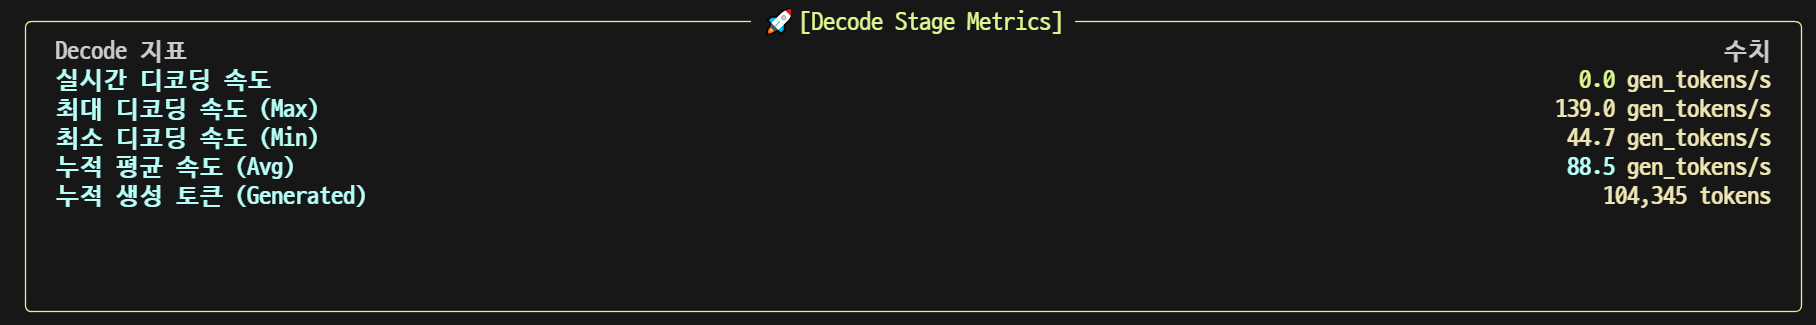
In the same environment, the numbers I couldn't even see when running with llama.cpp...
It seems to be a pretty good combination.
Reference: GPU power limit is 153W, memory is overclocked by +3000.

