[Claude Opus 5.5 Summary]
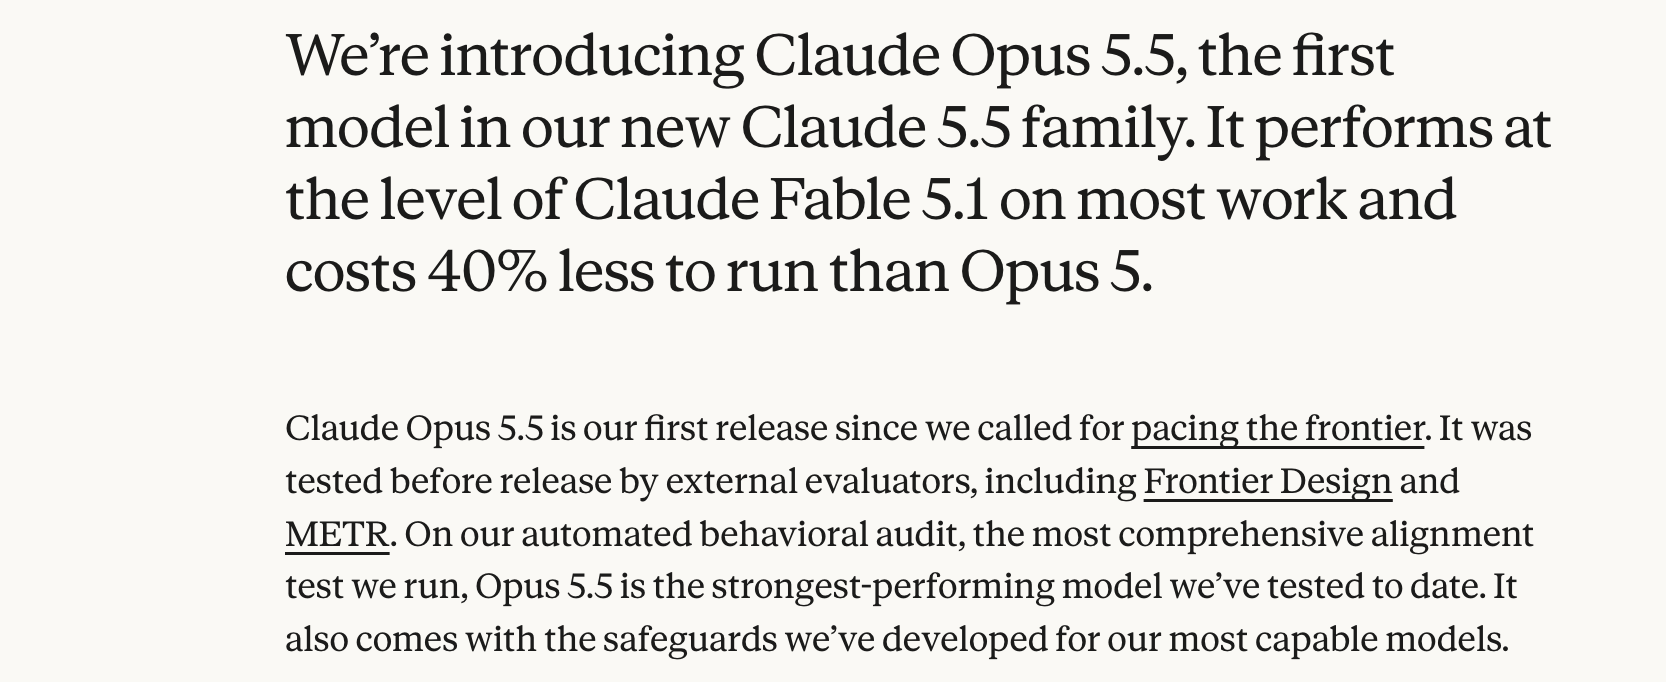
Claude Opus 5.5, released on September 22, 2026, is the first model in the Claude 5.5 product line. It achieves performance comparable to Claude Fable 5.1, a higher-performing model, while reducing operational costs for typical workloads by 40% compared to Opus 5. This model marks the first release since CEO Dario Amodei's call to "pace the frontier" – prioritizing safety measures over accelerating AI development.
Pricing has been reduced by 20%, with input costing $4 per million tokens and output costing $20 (Opus 5 was priced at $5/$25). Cache reads, which account for a significant portion of agent and coding task costs, have been reduced by 60% to $0.20 from $0.50, while cache writes have dropped to $5 from $6.25. This lower per-token cost, combined with fewer tokens used per task, results in an overall cost reduction of 40%. Output speed has also been increased by over 30%. Claude Code and Claude Platform now offer a Fast mode at input $8 and output $40, which is up to 2.5 times faster.
Anthropic claims that Opus 5.5 leads in agent coding, computer usage, and knowledge work benchmarks. In Terminal-Bench 4.0, it scored 66.4%, surpassing Fable 5.1 (55.8%), Opus 5 (52.3%), and GPT-6 Astra (57.9%). It also achieved a higher score of 1846 Elo in GDPval-AA, which evaluates performance across 44 professions, compared to Fable 5.1's 1735. However, GPT-6 Astra outperformed Opus 5.5 in business workflow (AutomationBench) and scientific research (Terminal-Bench-Science). Anthropic acknowledges that benchmark discrepancies may not accurately reflect real-world performance differences and suggests that the difference between Fable 5.1 and Opus 5.5 is smaller than the scores indicate.
The most notable advantage of Opus 5.5 is its efficiency. In medium effort settings, it surpasses the maximum effort setting of Opus 5 in Terminal-Bench 4.0 and achieves GPT-6 Astra's top score in FrontierCode at a fraction of the cost.
Opus 5.5 has also significantly improved writing capabilities. It prioritizes key information, uses less jargon and specialized terminology, and adheres to user-defined writing rules. This makes it easier to follow and review results even during lengthy tasks.
Safety measures have been enhanced with over 2,000 automated behavior audit scenarios. Opus 5.5 demonstrated the best results in most misalignment and honesty indicators among recent Claude models. The likelihood of taking irreversible or out-of-bounds actions has also been significantly reduced.
There are limitations to consider in real-world use. For the first time, Opus models have applied safety measures comparable to Fable 5.1 in cybersecurity, biology, and distillation domains. Requests falling under these categories are handled by other models.
Opus 5.5 is immediately available on all platforms, including AWS, Google Cloud, and Microsoft Azure. The API model name is claude-opus-5-5. For reference, this conversation is being handled by Opus 5.5.
▶ Original Source: https://www.anthropic.com/claude-opus-5-5